FTTH Network • Planning tools
How Much Fiber Do I Need for an AI Data Center GPU Cluster? A Calculator and a Method You Can Defend
Planners who ask how much fiber a GPU cluster needs often get a rule of thumb, such as “36 times a normal rack”. A usable answer has three parts: fibers per node, the fiber-km a cluster order consumes, and a date, because in 2026 cabling can have a lead time longer than the build. This page gives the method, a calculator you can run on your own numbers, and the wording to explain the result to a board, a customer or a network team. The defaults are illustrative, so replace them with figures from your own design.
Quick answer: With this page’s illustrative defaults, a 1,024-GPU cluster on a two-tier non-blocking fabric needs about 1,184 fiber-km, roughly 19.9 cable-km on 313 cable assemblies. Three things decide the number.
- Fibers per link: the input to verify first. The same cluster needs about 439 fiber-km with duplex links and about 2,216 with 16-fiber links.
- Fabric design: a third tier raises the order to about 1,872 fiber-km, and spine-leaf links roughly equal GPU count in a two-tier non-blocking design.
- Date: reported lead times run from about 12 weeks to a year, and a 20-week lead time leaves only 8 days of margin against a 15 April 2027 start.
In this page, fiber-km is every fiber strand multiplied by its length, and a cable assembly is one cable made for one run. A leaf switch connects GPU nodes and a spine switch connects the leafs. A non-blocking fabric has as much uplink as downlink bandwidth, and oversubscription is the ratio when it has less. A scalable unit is a repeatable block of nodes, 32 nodes or 256 GPUs in NVIDIA’s H100 reference. Slack is extra length for service loops, and a call-off is one scheduled delivery of a larger supply order.
How much fiber does your cluster need? Run the numbers
Enter the numbers you know and the page returns fiber-km, cable-km, cable assemblies and a buy-by date. Start with GPU count and fibers per link from your bill of materials, then set tiers and oversubscription from your fabric design. Open the advanced assumptions to change run lengths and buffers. Every default is an illustrative placeholder.
| Layer | Order fiber-km | Order cable-km | Cable assemblies |
|---|---|---|---|
| GPU to leaf | 343.9 | 4.8 | 139 |
| Leaf to spine | 687.7 | 2.4 | 35 |
| Storage and management | 152.8 | 12.7 | 139 |
| Total | 1,184 | 19.9 | 313 |
128 nodes, each on a 72-fiber cable for compute (71 fibers with spares); 32 leaf switches, each on a 288-fiber cable toward the spine (282 with spares).
Buy-by date: order by 29 Oct 2026 to start on 15 Apr 2027, 24 weeks earlier (20 weeks lead time plus 4 weeks buffer). That is 8 days from today.
Show the formulas
- Nodes and leafs: GPUs ÷ GPUs per node, and GPUs × links per GPU ÷ GPU-facing ports per leaf, both rounded up.
- Fibers per run: GPU to leaf = GPUs per node × links × fibers per link; leaf to spine = ports per leaf × (tiers − 1) ÷ oversubscription × fibers per link; storage and management = ports × fibers per port.
- Cable size: fibers per run × (1 + spare), rounded up to the next standard size (12, 24, 48, 72, 96, 144, 216, 288; above 288, multiples of 288).
- Fiber-km: runs × cable fibers × run length × (1 + slack).
- Cable-km: fiber-km ÷ cable fibers (at most 288 per cable), because each node and leaf gets its own cable.
- Order: base × (1 + waste) × (1 + contingency). Assemblies = order cable-km ÷ one run length (with slack), rounded up.
- Buy-by date: cluster start minus (lead time + buffer) in weeks.
Each node and leaf gets its own cable here. A third tier is modelled as one more full set of leaf uplinks, which simplifies a real core design, and the out-of-band management port is not counted. Short links are often copper or active optical cables, which this page does not count. Confirm the result against your fabric design before you commit to quantities.
Where does the fiber go in a GPU cluster?
Almost all of it sits in the compute fabric, and the number of links, not the number of racks, drives it. Each GPU has its own fabric link, and a non-blocking leaf-spine design adds roughly one more link per GPU between leaf and spine. At the defaults, 1,024 GPUs sit in 128 nodes of eight and are served by 32 leaf switches with 32 GPU-facing ports each. Each node needs 71 fibers with spares, a 72-fiber cable, and each leaf needs 282, a 288-fiber cable toward the spine. The spine side adds 1,024 links, one per GPU.
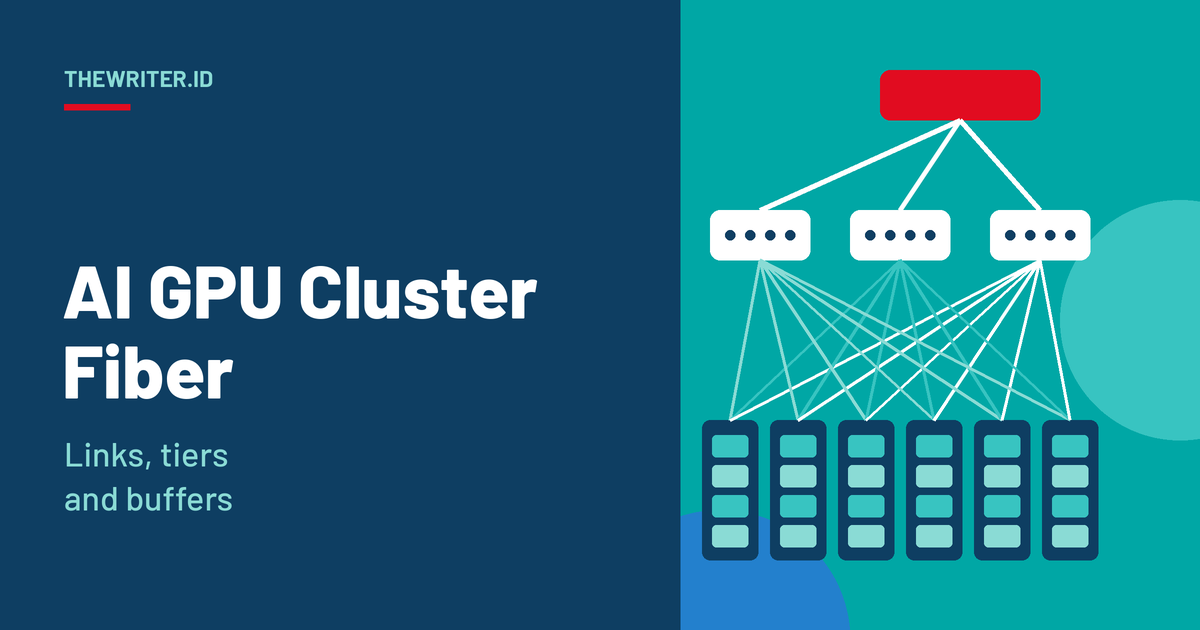
Figure 1 shows the structure. NVIDIA’s DGX SuperPOD reference architecture for DGX H100 describes a rail-optimized, full fat-tree compute fabric with eight 400 Gb/s connections per DGX H100 node, and groups nodes into scalable units of 32. Its network fabrics page lists 1,024 spine-leaf cables and 1,020 compute and UFM cables for the four-unit, 1,016-GPU configuration, so spine-leaf links roughly equal GPU count, as the 1,024 links in this model do. Storage and in-band management each use a pair of ports per node on separate fabrics. At the defaults, the leaf-to-spine layer holds 58% of the order. For conventional racks, compare fiber cabling per data center rack.
Figure 2 puts the count in context. Adding each node’s compute links, its storage and management ports and its share of the leaf-to-spine layer, a GPU node lights 136 fibers at these defaults, or 17 per GPU. A conventional server with two duplex ports lights 4. The 34 times ratio sits close to the 36 times that an STL executive was quoted as saying for AI data centers, as Tom’s Hardware reported in May 2026. The match depends on assuming 8 fibers per link, so read it as a sanity check, not proof. Links between sites are sized like a metro ring.
| Layer | Fibers carried | What sets the length | Common mistake |
|---|---|---|---|
| GPU to leaf | GPUs per node × links × fibers per link | Node to leaf, by tray route | Counting one fiber pair per GPU when the optic uses 8 |
| Leaf to spine | Leaf uplinks × fibers per link, once per tier above the leaf | Leaf row to spine row | Ignoring the 288-fiber step, which can double the cable |
| Storage and management | Ports per node × fibers per port | Node to storage or management switch | Forgetting that these fabrics are separate from compute |
Fiber type and optics are the other half of the specification. NVIDIA’s documents do not state the cable type or the fibers per link, so read the optic datasheet. A 400G DR4 module uses 8 fibers, four transmit and four receive, on an MPO-12 connector, according to a transceiver vendor’s explainer, which is a secondary source. The Ethernet standard behind 400G, IEEE 802.3bs, was approved in December 2017, and single-mode fiber is defined by ITU-T G.652. Tom’s Hardware also reported that manufacturers have shifted output from G.652D toward G.657A fiber, so confirm which category your supplier can deliver.
How much extra should you order beyond the fibers you light?
Order for the lit fibers plus five adjustments, and test where your numbers sit against the standard cable sizes. In this example the adjustments take 819.2 lit fiber-km to a 1184.4 fiber-km order, and raising spares from 10% to 13% can add 68% because it crosses a cable-size step.
| Adjustment | What it covers | How it gets underestimated |
|---|---|---|
| Spare fibers | Dark fibers for repairs, test and the next link speed | Set as a round percentage without checking the cable-size steps |
| Standard sizes | Cables exist at set counts, so a node that needs 71 fibers gets 72 | Left out of the quantity, then found on the invoice |
| Slack | Service loops, tray bends and patch-panel entry | Set low because rows look short on the floor plan |
| Waste | Cut-to-length offcuts and damaged assemblies | Assumed zero for factory-terminated cables |
| Contingency | Design changes and re-pulls after link test failures | Treated as padding |
Re-pulls are the part of contingency teams rarely price, because every failed link test sends a technician back with a new cable, and a cluster has thousands of links. The Technician Checklist Generator turns your acceptance tests into a checklist crews actually follow, which is the cheapest way to lower that number.
Figure 3 builds the order one step at a time. The fibers actually lit come to 819.2 fiber-km; the order is 1,184.4. Slack adds 142.8 fiber-km, the most of any step, because the runs are long and every one gets the 15%. Standard sizes add only 46.1 because 71 and 282 fibers land just under the 72 and 288 steps. That is luck, not safety.
Figure 4 moves one input at a time. Fibers per link dominates: 20% fewer (6 instead of 8) cuts the order by 14.5%, while 20% more (10 instead of 8) adds 67.7%, because 32 uplinks of 10 fibers with spares no longer fit one 288-fiber cable. Spares are the trap. At 8% or 12% they change nothing, yet at 13% the leaf cable doubles to two 288-fiber cables and the order rises 68%, from 1,184 to 1,987 fiber-km.
| Design | Cable per node | Cable per leaf | Order fiber-km | Assemblies |
|---|---|---|---|---|
| Two tiers, 2-fiber links | 24 fibers | 72 fibers | 439 | 313 |
| Two tiers, 8-fiber links (default) | 72 fibers | 288 fibers | 1,184 | 313 |
| Two tiers, 16-fiber links | 144 fibers | 576 (2 x 288) fibers | 2,216 | 348 |
| Three tiers, 8-fiber links | 72 fibers | 576 (2 x 288) fibers | 1,872 | 348 |
| Two tiers, 2:1 oversubscribed, 8-fiber links | 72 fibers | 144 fibers | 841 | 313 |
The fabric design moves the answer as much as the optics: a third tier adds about 58% and a 2:1 oversubscribed fabric saves about 29%. Fiber itself is a small part of the cost. At the roughly $6.30 per fiber-km that Tom’s Hardware reported, the 1,184 fiber-km in this order is under $8,000 of bare fiber, so the risk is delivery, not the glass price.
When do you need to buy the fiber?
Work backwards from cluster start: buy-by date equals start date minus supplier lead time minus a shipping and QA buffer, and treat the lead time as a number to confirm, not assume. The reports below describe the market in general and some rest on a single source, so use them to set expectations and then get written quotes.
In May 2026, Tom’s Hardware reported that fiber demand from data centers grew 76% in 2025, citing CRU data, that prices rose about 70%, and that lead times reached up to 20 weeks for large-volume buyers and up to a year for smaller ones. It reported that two large Chinese suppliers, Hengtong and FiberHome, were booked into early 2027. CRU Group’s OFC 2026 review names preform as the binding constraint and says ribbon cables for AI data centers, from 1,000 to over 13,000 fibers, carry lead times over a year. Those are market reports, not quotes to you.
Figure 5 applies those lead times to an example plan. If you order on 21 October 2026 with a 20-week lead time and a four-week buffer, the earliest start is 7 Apr 2027, only 8 days ahead of a 15 April 2027 cluster start. At 52 weeks the earliest start is 17 Nov 2027, about 31 weeks late. With so little margin, any slip in a quote moves the cluster date, which is why the buy-by date matters more than the exact fiber-km.
Figure 6 shows one way to cut exposure: one call-off per 256-GPU scalable unit. NVIDIA’s table shows spine-leaf cables growing by 256 with each unit, from 256 to 1,024, which supports building and cabling in units. In this example, four call-offs cut the peak quantity on site from 1,184 to 296.1 fiber-km. The catch is commitment: phasing only protects you if the supplier agrees in writing to hold allocation for every call-off.
How do you explain the number to a board, a customer or a network team?
Write the consequence, not the parameter. Every figure on this page becomes a sentence someone else has to accept: a board approving a purchase order, a customer told a go-live date has no slack, a network team told why a spare allowance was capped. Engineers tend to write these as parameters. Readers need to know what changes for them and what you have secured. When a fabric change goes wrong, the Outage Message Generator drafts the customer update in the same plain style. The examples below use this page’s illustrative numbers.
Telling the board why cabling is now a line item
Telling a customer the go-live date depends on cable
Telling the network team why the leaf cable is capped at 10% spares
What should you check before placing the order?
Confirm eight things, and write down who owns each.
- GPU count and phasing match the approved design, by scalable unit, not the sales forecast.
- Fibers per link come from the optic datasheet and the bill of materials, not from a reference design that does not state them.
- Fabric tiers and oversubscription are fixed, because a third tier or a changed ratio changes every leaf cable.
- Every cable sits clear of a standard-size step, or the step is a recorded decision.
- Node-to-leaf and leaf-to-spine runs are measured along the tray route, not drawn as straight lines.
- Lead time is in writing for each cable type and states whether the date is shipment or delivery.
- Call-offs are planned by scalable unit, and the supplier has committed allocation for each one.
- Link acceptance tests are agreed before the first delivery. The Technician Checklist Generator can turn them into a checklist crews use.
Frequently asked questions
How much fiber do I need for an AI data center GPU cluster?
With this page's illustrative defaults (1,024 GPUs in 128 eight-GPU nodes, a two-tier non-blocking fabric, 8 fibers per link), the cluster needs about 1,184 fiber-km, roughly 19.9 cable-km on 313 cable assemblies, including 10% spare fibers, 15% slack, 3% waste and 5% contingency. The biggest unknown is fibers per link. With duplex 2-fiber links the same cluster needs about 439 fiber-km, and with 16-fiber links about 2,216.
How many fibers does each GPU need?
At the defaults, each eight-GPU node lights 136 fibers once you add its compute links (64), its storage and management ports (8) and its share of the leaf-to-spine layer (64). That is 17 per GPU, against 4 fibers for a conventional server with two duplex ports. The 34 times ratio is close to the 36 times that an STL executive was quoted as saying for AI data centers, but the match depends on the 8-fiber link assumption, so treat it as a sanity check, not a validation.
Does a third tier or oversubscription change the fiber count?
Yes. Adding a core tier raises the order from about 1,184 to about 1,872 fiber-km in this model, because every leaf needs a second set of uplinks and the cable crosses the 288-fiber step. A 2:1 oversubscribed fabric halves the leaf uplinks and cuts the order to about 841 fiber-km, at the cost of bandwidth between racks. Whether that trade is acceptable is a network design decision, not a purchasing one.
What do NVIDIA's reference designs say about cable counts?
NVIDIA's DGX SuperPOD reference architecture for DGX H100 lists, for its largest tested configuration of 4 scalable units, 127 nodes, 1,016 GPUs, 32 leaf and 16 spine switches, 1,020 compute and UFM cables and 1,024 spine-leaf cables. So spine-leaf links roughly equal GPU count, as in this model. The document does not state the cable or optic type or the fibers per link, so fibers per link is an input you must take from your own bill of materials.
Why can a small change in spares double the leaf cable?
Cable counts are standard steps. At the defaults a leaf switch has 32 uplinks of 8 fibers, or 256 fibers, and 10% spares make 282, which fits one 288-fiber cable. Above 12.5% spares the need passes 288 and the leaf needs two cables, so at 13% the order jumps from about 1,184 to about 1,987 fiber-km. Check where your numbers sit relative to these steps before you finalise the spare allowance.
When should I order fiber for a GPU cluster?
Work backwards from the cluster start date: buy-by date equals start date minus supplier lead time minus a shipping and QA buffer. Tom's Hardware reported in May 2026, citing Data Center Dynamics, lead times of up to 20 weeks for large-volume buyers and up to a year for smaller ones. Those are reports, not quotes to you, so get a written lead time for each cable type from your own suppliers, and plan call-offs by scalable unit if you can.
Sources
- NVIDIA documentation, last updated 19 November 2025, NVIDIA DGX SuperPOD reference architecture for DGX H100: components: rail-optimized, full fat-tree compute fabric with eight 400 Gb/s connections per DGX H100 node; scalable units of 32 nodes.
- NVIDIA documentation, last updated 19 November 2025, NVIDIA DGX SuperPOD reference architecture for DGX H100: network fabrics: Table 4 cable counts for 1 to 4 scalable units (1,020 compute and UFM cables and 1,024 spine-leaf cables at 4 units). Cable and optic types are not stated.
- Tom’s Hardware, Luke James, 16 May 2026, AI data centers are consuming fiber optic cable faster than suppliers can make it: 36x claim, 76% demand growth, price rise, lead times, 18 to 24 months for preform capacity, Hengtong and FiberHome booked into early 2027, shift from G.652D to G.657A. Several figures are quoted from other outlets.
- CRU Group, Egest Balla, 14 April 2026, Key takeaways and trends from the OFC 2026 conference: preform as the binding constraint; ribbon cables of 1,000 to 13,000 fibers with lead times over a year.
- Fluxlight blog (transceiver vendor), 23 November 2022, 400G DR4 QSFP-DD optical transceiver: 400G DR4 uses 8 fibers on MPO-12. A transceiver vendor blog, so a secondary source.
- IEEE 802.3 Working Group, IEEE P802.3bs 400 Gb/s Ethernet Task Force: 400 Gb/s Ethernet task force; IEEE 802.3bs approved December 2017.
- ITU-T, edition 08/24, in force, G.652: Characteristics of a single-mode optical fibre and cable: single-mode fiber.
All GPU counts, fibers per link, run lengths, buffers, the 4-week shipping buffer and the 12-week case are illustrative placeholders for this page, not published data. NVIDIA’s documents do not state cable or optic types. The lead-time and price reports above describe the wider market and several are quoted second-hand, so they may not reflect your supplier.